


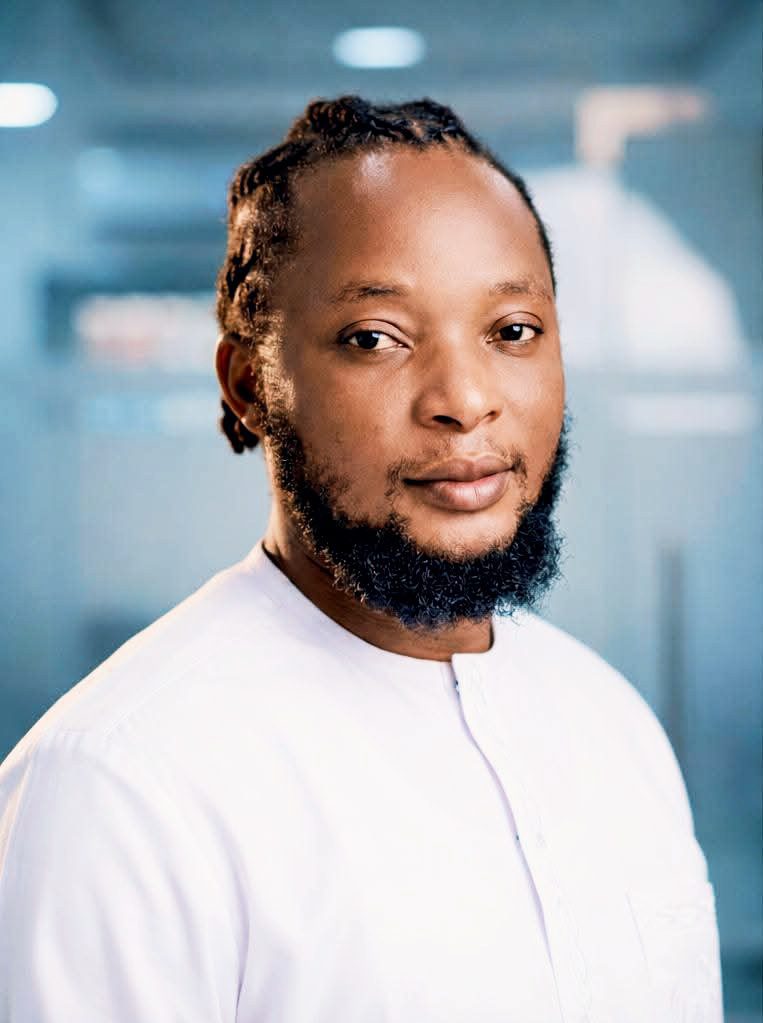
If you ask Spitch’s Temi Babs what happens if OpenAI or ElevenLabs wake up tomorrow and decide African languages are worth a serious push, he would answer without flinching. He tells you they’d have to go through him first.
That is a bold claim for a founder who, by his own admission, has “raised very little money,” but that’s precisely the argument the Spitch founder and CEO wants on the record: that in voice infrastructure for the continent’s languages, capital is not the moat everyone assumes it is.
“I understand this so well because we’ve bootstrapped to get this far ahead,” he told Technext in an exclusive interview.
“Capital is valuable, but it is not the moat many people assume it is. We have bootstrapped Spitch to this point, which has forced us to build efficiently and stay close to the problem. Funding would help us move faster, particularly in data acquisition, model development and distribution. But it would amplify the advantage we have already built rather than create it,” he said.
He lets the sentence trail before landing the real point: “any well-funded global giant trying to serve African markets would need the relationships, the data and the understanding of the mindset of the average Nigerian, the average West African or East African” that Spitch has spent two years accumulating. “You can’t beat that with billions of dollars.”
Spitch didn't start out trying to be Africa's voice layer. It started in 2024 as a note-taking tool built for students, designed to record lectures and convert them into structured summaries and action points. The idea collapsed almost immediately on contact with the African classroom.
Lecturers switched between Yoruba, Igbo and English mid-sentence. Some spoke Pidgin. Some blended two languages in the same breath, over a backdrop of classroom noise no clean training set had prepared for. “It was impossible for that use case for that product to actually work in the African context,” Babs said.

Rather than abandon the project, the team treated the failure as a signal. If transcription broke down that badly for lecture halls, the underlying problem- getting machines to reliably hear, understand and speak African languages- was bigger than education.
It was infrastructure.
The pivot happened fast enough that Spitch had signed a paying customer a week before its official product launched in October 2024, a detail Babs still seems pleased about. “That gave us validation for the products we’re building.”
Spitch’s numbers in two years
Two years on, Babs puts Spitch’s footprint at roughly 1,800 developers, four enterprise clients and fifteen mid-sized businesses running their customer communications through the platform.
Between the October 2024 launch and October 2025, the company processed a million seconds of audio; cumulative volume has since climbed to nearly three million, with Babs estimating current monthly throughput at 300,000 to 400,000 seconds.
Named enterprise clients include Safaricom Ethiopia and Nigerian news publication Leadership, alongside what Babs described as several smaller business-to-business partnerships. The use cases, he was candid to admit, aren’t especially exotic: inbound and outbound customer support and delivering content to customers in their own languages.
“Nothing is really surprising from what we have seen,” he said, “as long as you tie it to the core fundamental needs of the business.”
Ask Babs what’s actually hard about this, and the answer isn’t the model architecture. It’s the data. “Compute is to a large extent limited by how much money you have,” he explained. “But data is a different story. There are policies and regulatory frameworks around how you handle and manage data.” That, he argued, makes data acquisition harder than the compute problem by “one or two levels”.
Spitch’s approach to solving it evolved in three stages: the founding team initially recorded their own voices to train early models, then licensed labelled datasets from partners covering individual languages like Hausa, Igbo, Yoruba and Amharic. The current model has Spitch partnering directly with enterprise clients, using their existing voice data to fine-tune models that get deployed back into their own environments.
The company can technically support more than 400 languages, inherited from the broader infrastructure it builds on, but actively trains and maintains strong support for around fifteen to twenty across West and East Africa.

With Nigeria’s 2027 elections approaching and a recent incident in which a presidential spokesperson circulated what turned out to be an AI-generated video, the ethics of voice cloning aren’t hypothetical for Spitch.
Babs said every piece of audio the platform generates is cryptographically signed, so provenance can be checked against any file in question. Beyond that, he’s leaning on public education: “Work with the assumption that anything you see online could be fake; don’t believe it immediately unless it’s coming from that person directly.”
On regulation, Babs is measured rather than combative. Nigeria’s National AI Strategy and emerging data protection frameworks are, in his reading, “quite inclusive” of local builders so far.
His worry is timing: governments “over-engineer things too early”, stacking compliance requirements onto companies before the technology or the harms are well understood.
Babs is visibly allergic to being called “the ElevenLabs of Africa”. He argues that framing a voice AI company by geography undersells what it does: “Africa is communicating with the rest of the world. Africa is not in isolation.” Spitch, in his telling, isn’t a regional clone chasing a global original; it’s infrastructure for languages the rest of the world has ignored, full stop.
Whether that framing survives contact with a well-capitalised competitor entering the market remains to be tested.
But Babs isn’t hedging on where he expects to be in five years: involved in at least a third of all voice communication across Africa. “Voice is not just a way to communicate,” he said. “It is our identity, our culture. It is how we live.”
